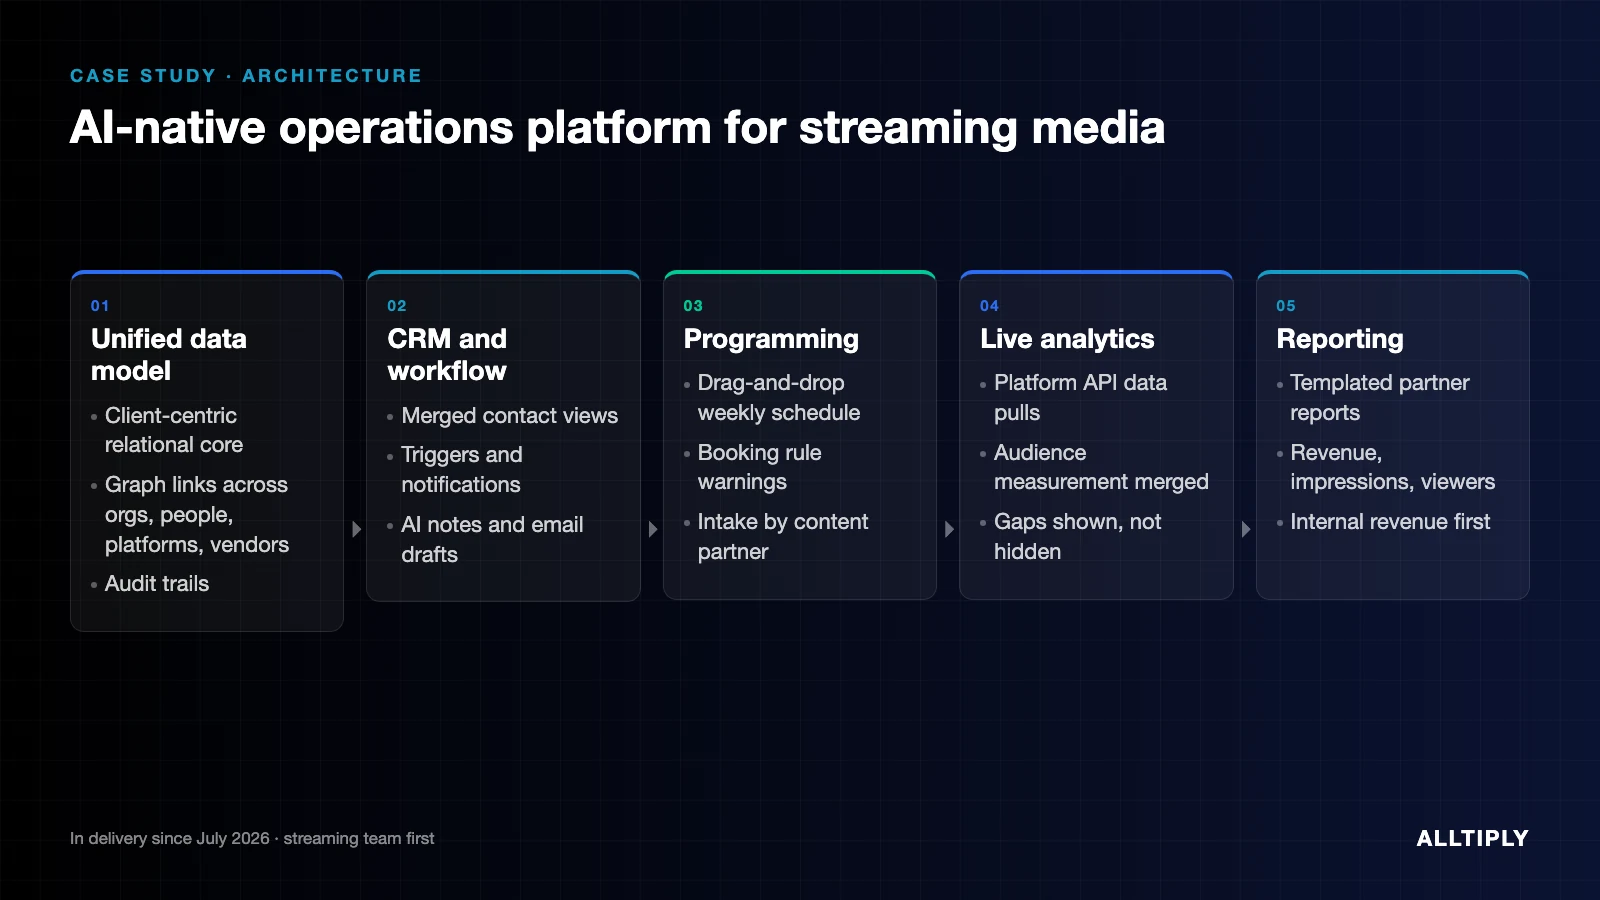
Expected value, implementation cost, and the measurement method are agreed before development begins.
Milestones are set around data readiness, integrations, security review, and the production environment.
Current cost, cycle time, quality, capacity, or risk is established before improvement is measured.
Results are reported against approved source data, a defined system boundary, and an agreed measurement period.

A help assistant that is slow or right only some of the time teaches people to stop asking it. The cause is usually structural: how documents were split, which embeddings are used, and how much context each question gets. Prompt tuning on top of that goes only so far.
ALLTIPLY builds retrieval systems that classify each question first, search with hybrid keyword and vector retrieval, serve human-approved answers before generated ones, and cite every source. The retrieval method is written up in Intent-aware retrieval. See how we rebuilt one in our enterprise product help assistant case study.


Four phases from a locked benchmark to an assistant in production behind an evaluation gate.
We agree the question set, audiences, metrics, and comparison date in writing, and measure the current system so every later change is judged against the same baseline.
We re-chunk content around its real structure, tune embeddings to your vocabulary, add hybrid search with rank fusion and a reranker, and map shorthand and codes to the right product.
We add intent classification, per-intent context budgets, the approved-answer tier with a tuned match threshold, cited generation, and checks on critical details before they appear.
Retrieval and answer metrics run in the release process, the approved-answer library gets owners and a review loop, and your team gets the documentation to keep improving it.