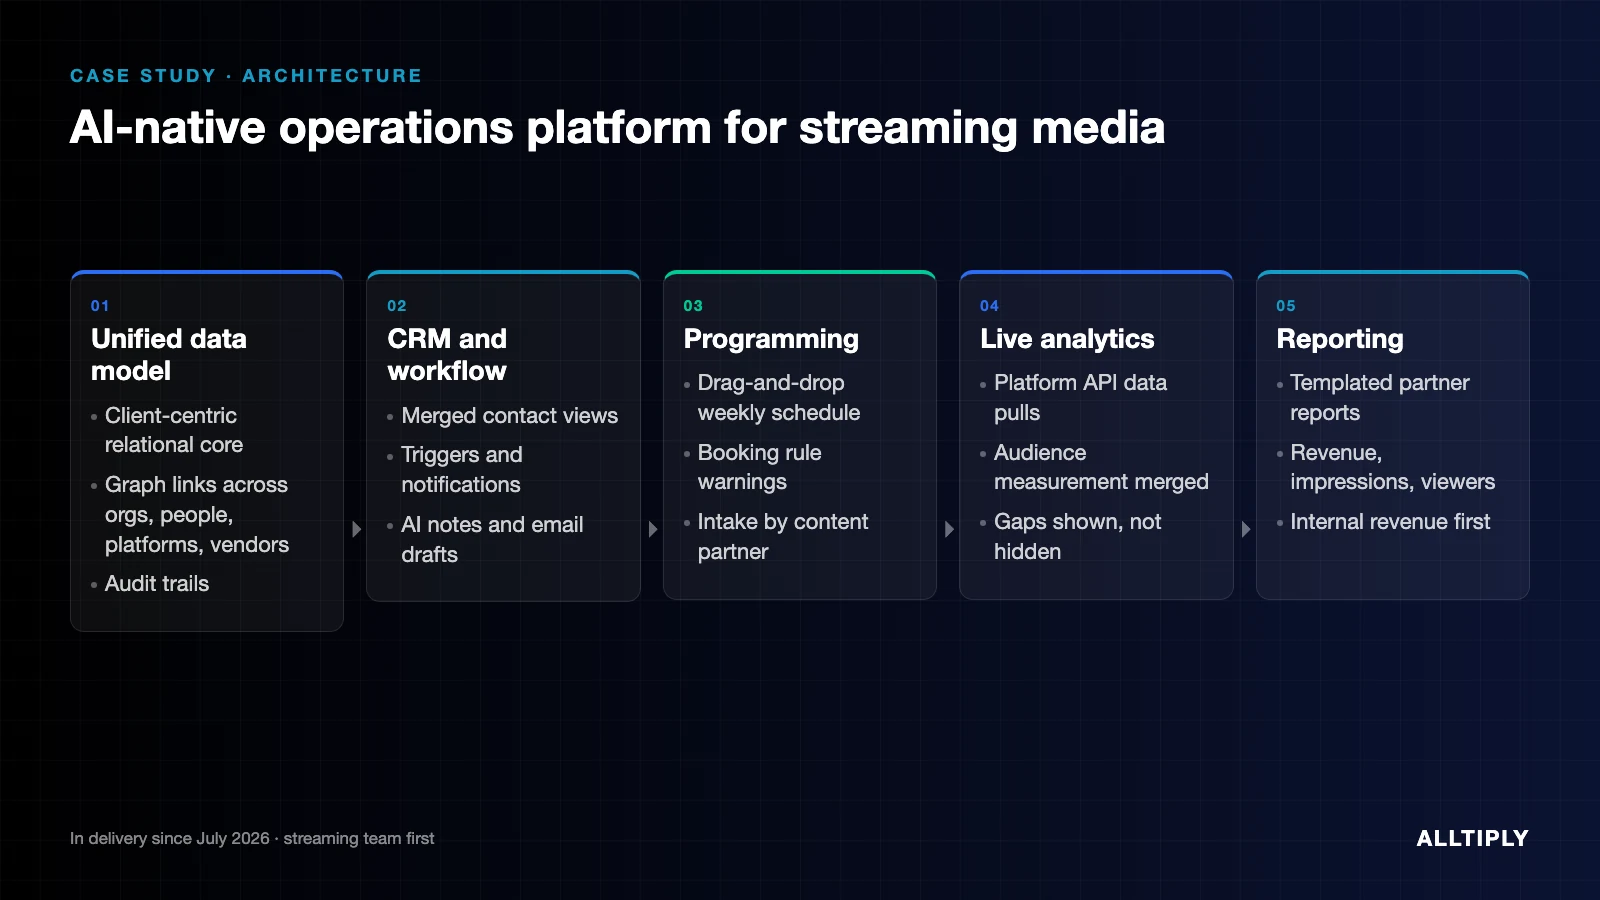
Expected value, implementation cost, and the measurement method are agreed before development begins.
Milestones are set around data readiness, integrations, security review, and the production environment.
Current cost, cycle time, quality, capacity, or risk is established before improvement is measured.
Results are reported against approved source data, a defined system boundary, and an agreed measurement period.

Most training measures attendance. A rep can finish every module and still fumble the message in front of a skeptical buyer. ALLTIPLY builds voice AI platforms where people practice real conversations against an AI counterpart, get scored against a rubric you control, and certify on performance instead of completion.
We ground every scenario in your own documents and positioning, calibrate the AI grader against human grades, and keep a trainer override in place until agreement is measured. Our method is written up in Calibrating AI graders. See it in production in our voice AI sales roleplay platform and AI-scored voice sales certification.


Four phases from scoping the program to a calibrated certification running in production.
We define the audience, tiers, pass rules, and weighted criteria with your enablement leads, and agree how scoring will be checked before anyone is certified.
We ingest your documents and positioning, tag them for relevance and region, and build scenarios with an AI counterpart that raises the objections your people actually hear.
Trainers grade a reference set of transcripts and we tune the AI grader until it matches them. Leaders then take the program themselves before the field does.
We roll out to cohorts in waves, fix invitations and roles between waves, and give managers team-level reporting on who has started, who is stuck, and who has passed.